
Pipelines
An overview of the Stroom pipeline model, elements, and data flow.
In Stroom, a Pipeline is a configurable sequence of processing steps used to parse, transform, and store data. Think of it as a "factory assembly line" where raw data enters at one end and refined, structured data comes out the other.
Core concepts
Elements and links
A pipeline is composed of Elements. Each element performs a specific job: reading a file, parsing text, transforming XML using XSLT, or writing to a database.
- Elements: The individual "machines" in the factory.
- Links: The "conveyor belts" that connect one element to the next, defining the direction of data flow.
For more details on specific elements, see Pipeline Elements.
The streaming model (SAX)
Unlike many systems that load an entire file into memory (DOM), Stroom uses a SAX-style streaming model. Data flows through the pipeline as a series of "events" (e.g., Start Element, Characters, End Element). This allows Stroom to process massive multi-gigabyte files with a very small and stable memory footprint.
Anatomy of a typical pipeline
A common pipeline for ingesting data usually follows this sequence:
- Reader: Reads the raw bytes from a stream.
- Parser: Converts the raw text into XML events (see Parsers and translation). The most common parser is the DSParser, which uses a Text Converter to turn CSV or log files into XML.
- Filter: Acts on the XML events. The most powerful filter is the XSLTFilter, which uses XSLT to transform the structure of the data. This includes tasks like renaming fields, adding timestamps, or performing lookups. Filters reference a XSL Translation document.
- Writer: Formats the XML events back into a specific format (e.g. XMLWriter or JSONWriter).
- Appender: Saves the final output to a destination. This could be another stream (StreamAppender), a search index (IndexingFilter), or a file.
To build one step by step, see Your first translation.
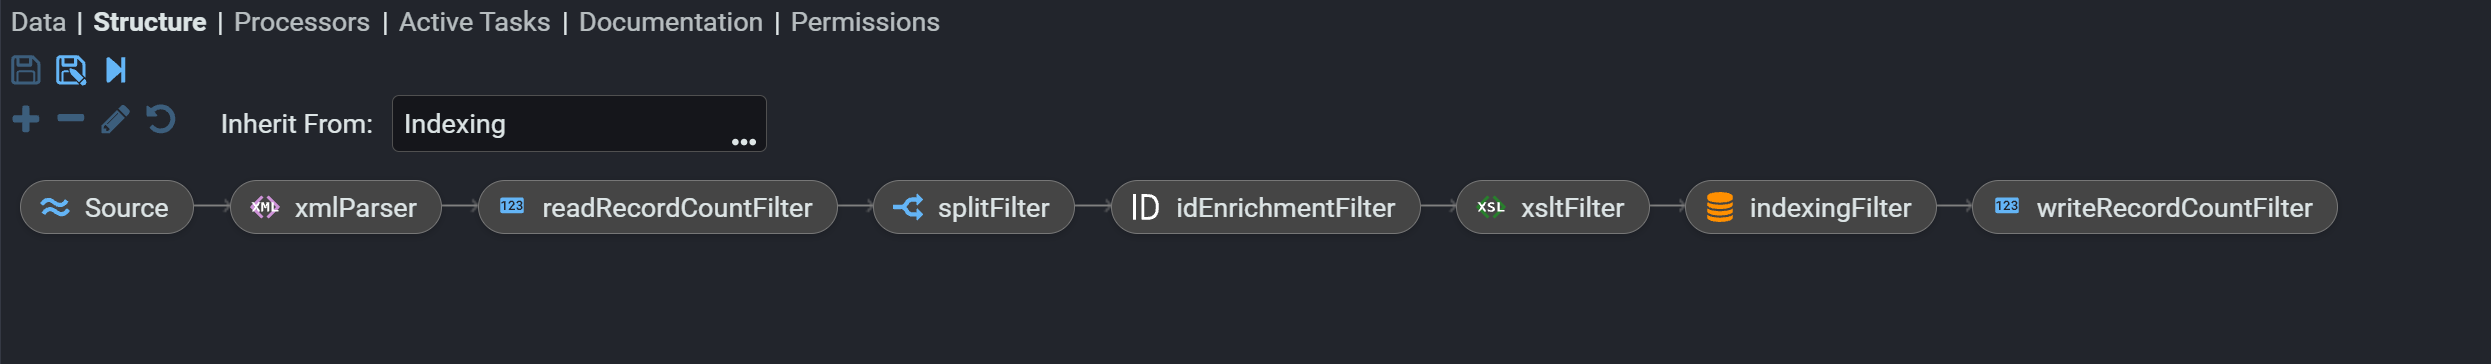
Pipeline inheritance
One of Stroom's most powerful features is Inheritance. You can create a "Base" pipeline that contains common elements (like the Reader and Parser). Then you can create multiple "Child" pipelines that inherit those elements but add their own specific XSLT transformations.
- Benefit: If you need to change the parsing logic for a specific log format, you change it in the Parent pipeline once. All Child pipelines are updated automatically.
How data flows
When a pipeline runs, data moves through three distinct phases:
| Phase | Description |
|---|---|
| Input | The pipeline fetches data from a Feed (see Pipeline data sources). |
| Processing | Elements parse and transform the data according to the pipeline's configuration. |
| Output | The resulting data is written to a new Stream, an Index, or an external system (see Pipeline data destinations). |
The stepper: seeing inside the pipe
Because pipelines can be complex, Stroom Feeds provide a tool called the Stepper . It allows you to "step" through the data record by record. You can see the input and output of every single element in the pipeline simultaneously. This makes it easy to identify exactly where a transformation might be failing. See Pipeline debugging.
You can find the button in the lower right-hand corner of the Feed Data page.
Pipelines run when a processor filter selects streams for them. See Processor filters and tasks, and Is data processing? if nothing seems to happen.
Summary
- Pipelines are modular: You build them by linking elements together.
- They are event-driven: They process data as a stream, not in bulk.
- They are reusable: Use inheritance to share logic across many feeds.