
The Datafeed Contract
The headers, compression, authentication and responses that every sender has to satisfy.
One endpoint, and everything that goes into and comes out of it. This is the interface every connector and adapter satisfies, whether it is a log shipper, a script, or something you wrote.
The endpoint
https://<stroom-host>/<base-path>/datafeed
The path part is /datafeed. Legacy noauth- and authenticated-prefixed aliases are also registered. The base path depends on how the instance is deployed, so confirm it with whoever operates it.
The endpoint exists on both Stroom and Stroom Proxy.
Request headers
| Header | Required | Notes |
|---|---|---|
Feed | Yes, unless feed name generation is enabled | The routing key, and a security boundary. See Choosing a feed |
Type | No | Stream type, e.g. Events, Raw Events |
Compression | No, but set it explicitly | ZIP, GZIP or NONE. See below |
EffectiveTime | No | Event time, as distinct from receipt time |
GUID | No | Client-supplied identifier, useful for tracing one post |
Other recognised keys a sender may usefully populate: System, Environment, Component, AccountId, AccountName, Format, Schema, SchemaVersion, Encoding, Classification, Host.
Compression
A compressed body can be declared in one of two ways, and exactly one of them must be used:
Compression, Stroom's own header, set toGZIPorZIP. Stroom decompresses the body itself.Content-Encoding: gzip, the standard HTTP header. Stroom's embedded web server inflates the body before the datafeed code sees it, so the stream is stored decompressed. This is what most HTTP clients and log shippers send when you turn their compression on.
Compression values are case-insensitive, and anything outside ZIP, GZIP and NONE is rejected outright with 406 and Stroom-Status 200, so a typo in the value is a hard failure rather than a silent one.
Never send both. If a request carries Content-Encoding: gzip and Compression: GZIP, the body is decompressed twice. The second attempt finds plain text where it expects gzip, and the post fails with 500 and Stroom-Status 400, Compressed stream invalid. That at least is loud, but it fails every post. So if your shipper's own compression option is on, leave Compression at NONE (or leave it out). Set Compression: GZIP only when the body is compressed by something that does not set Content-Encoding, such as a script that gzips a file before posting it.
Fails silently
A compressed body with neither header is stored as compressed bytes, and nothing ever complains.
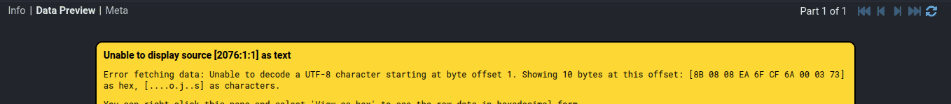
If Compression is missing, empty or NONE, and there is no Content-Encoding, the body is treated as uncompressed and stored as-is. The post returns 200, the stream appears on the feed, and the stream's Data Preview shows Unable to display source as text.
Processing does not catch it either. A text pipeline reading such a stream has been seen to produce an Events stream holding a single empty event, with no Error stream at all. The only reliable check is to open the raw stream and confirm it is readable text.
Authentication
Which methods are accepted is configured server-side, so ask whoever operates the instance. The available types are a data feed key, an OAuth token, a client certificate, or a certificate identity.
For third-party shippers, data feed keys are the practical choice: a single static header that every HTTP tool supports.
- The key travels in the standard
Authorizationheader. - The
Bearerprefix is optional. BothAuthorization: Bearer sdk_…andAuthorization: sdk_…work. Prefer theBearerform, since more tools have a first-class field for it. - Data feed keys are recognisable by their
sdk_prefix.
Mutual TLS works, but is markedly harder to configure in most agents. Choose it only if your tool already does mTLS elsewhere.
Never hardcode a key into a configuration file that ships in version control or is world-readable.
Responses
On success the response returns 200, and the response body is the receipt ID that identifies that one post, for example 1791981748008_0000_S_node1a. It is formed from the receipt time in epoch milliseconds, a sequence number, S for Stroom or P for Stroom Proxy, and the node name. There is no ReceiptId response header. The ID is stored on the stream as its ReceiptId attribute and appended to ReceiptIdPath; when the data passes through Stroom Proxy, each later hop replaces ReceiptId with its own ID, so it is ReceiptIdPath that keeps the one the sender was given.
On failure it carries Stroom-Status with a numeric code and Stroom-Error with the reason in words. Stroom Proxy reads Stroom-Error off its own downstream responses to log forwarding failures, and it is the quickest way to find out why a post was rejected.
A sender that records none of these cannot tell you why data is missing. Capture the response body and both headers. The full list is in Datafeed response codes.
Testing before wiring up a real sender
Prove the endpoint, the authentication and the feed with curl first. It isolates problems in your shipper's configuration from problems at the Stroom end:
curl -v -X POST "https://stroom.example.com/<base-path>/datafeed" \
  -H "Feed: MY_TEST_FEED" \
  -H "Type: Events" \
  -H "Compression: NONE" \
  -H "Authorization: Bearer ${STROOM_TOKEN}" \
  --data-binary @sample-event.txt
Expect 200, with the receipt ID as the response body. If it fails, read Stroom-Status and Stroom-Error before touching any agent configuration.
To prove the compression path specifically, gzip the file and send it with Compression: GZIP, then check in Stroom that the stored stream is readable text rather than binary. Omitting the header there is exactly the silent failure described above, and it is worth reproducing once deliberately so that you recognise it. If your shipper will send Content-Encoding: gzip instead, test that form with -H "Content-Encoding: gzip" and without Compression.
Formats
Stroom's pipelines already parse XML, XML fragments, JSON and arbitrary delimited or regex text. No sender needs to parse, normalise or reshape payloads: send events as close to their native form as possible and let the pipeline do the work. Keep every integration to transport and metadata.
One decision does have to be made per sender: whether a post body is one event or a batch, and if a batch, whether it is newline-delimited or a JSON array. The receiving pipeline's parser has to match.